BuildIndependently confirmed2 publishers2 min readPublished
Intel puts 1.3 PFLOPS of FP8 and 480GB of LPDDR5X on a 350W air-cooled card
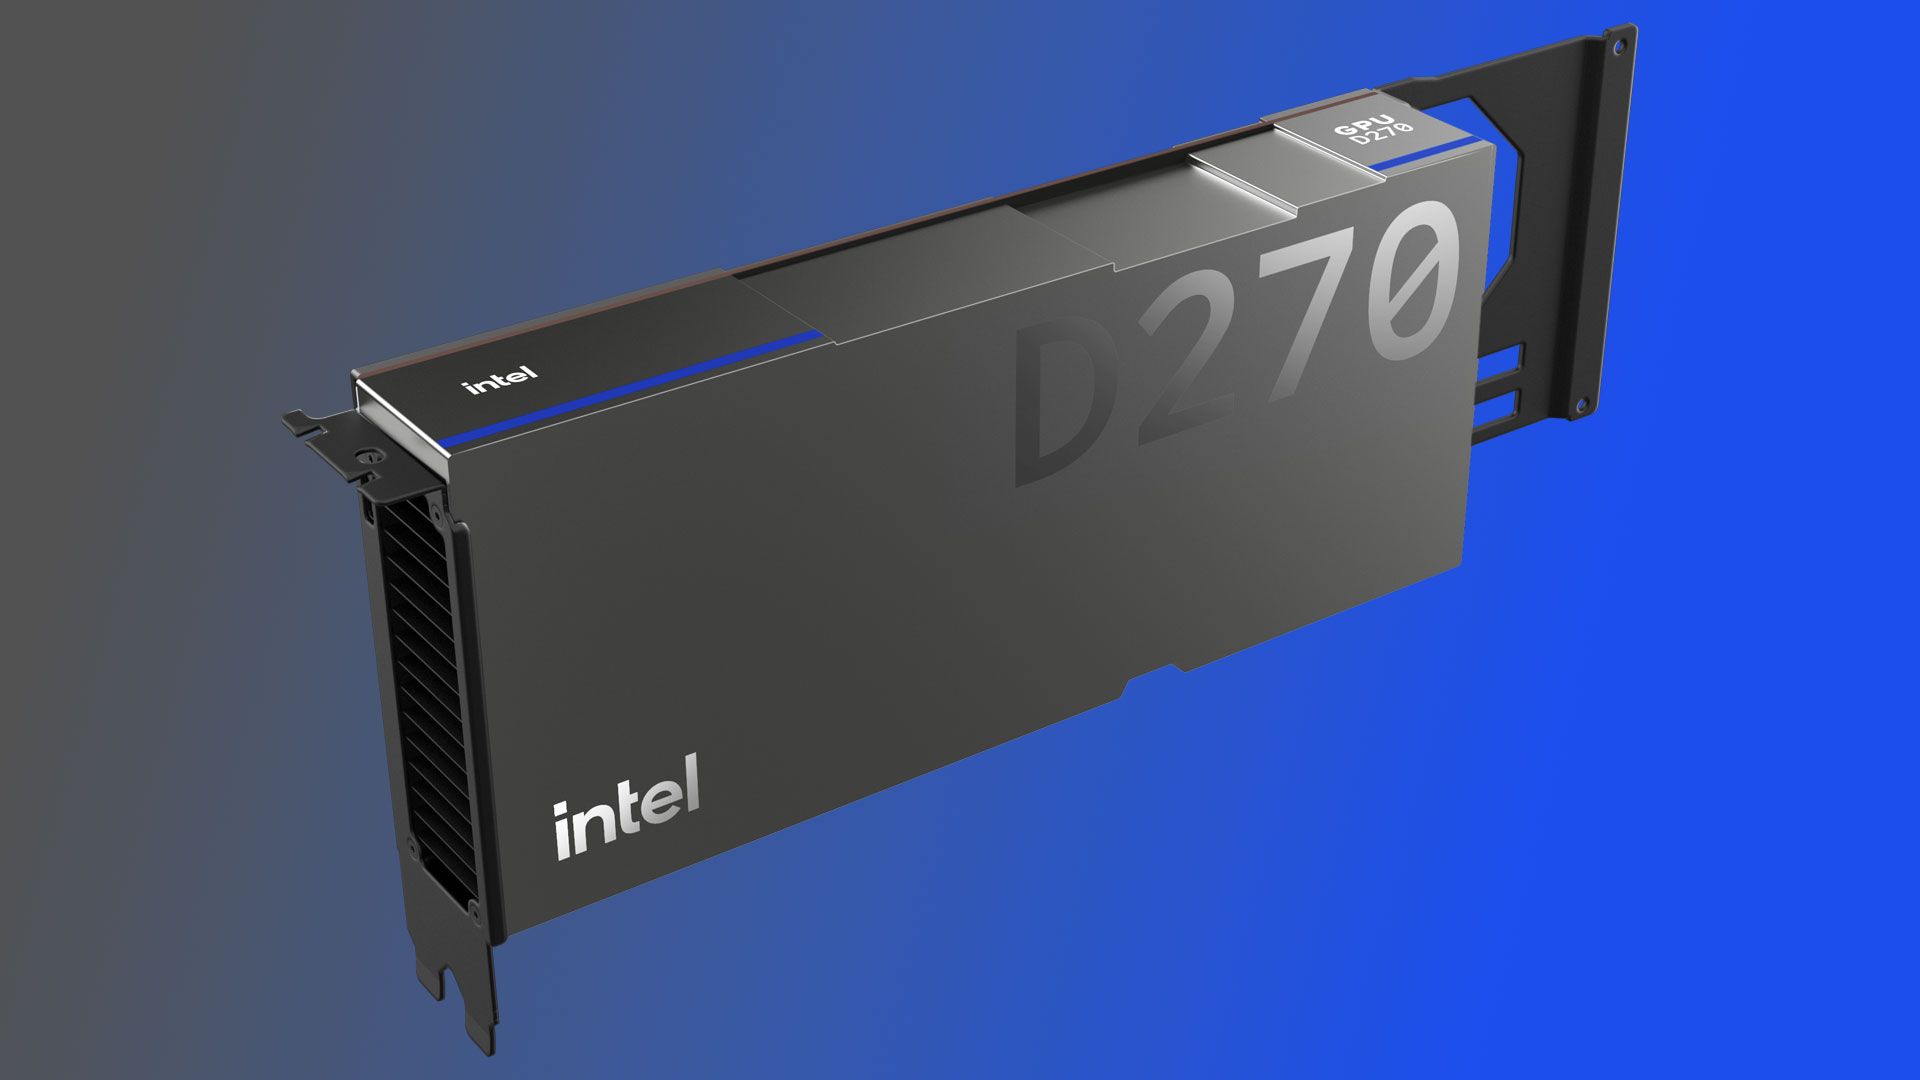
Intel named Crescent Island the GPU D-Series at OCP 2026, a 350W air-cooled PCIe card with up to 480GB of LPDDR5X. Tom's Hardware reported a 1.3 PFLOPS FP8 peak target and 1.5 TB/s of bandwidth; customer sampling is in progress.
The Engineer · Build desk
Three figures: about 1,000GB of weights is roughly 26% of 3,840GB; eight GPUs give 3,840GB of memory; the weights of a one-trillion-parameter model at 8 bits take about 1,000GB.
| Figure | Value | Note | Claim |
|---|---|---|---|
| 1,000GB of weights as share of 3,840GB | 26% roughly | 20 | |
| Memory across eight GPUs | 3,840 GB | 18 | |
| Trillion-param model, 8-bit | 1,000 GB, about | 19 |
What happened
- Phoronix lists the flagship as the Intel GPU D270, with PCIe 5.0, 32 Xe3P cores and 256 XMX Xe3P matrix engines.
- Intel intends the cards for traditional air-cooled rack servers of up to eight GPUs, in the style of Nvidia's HGX systems.
- Tom's Hardware says Crescent Island is the first chip built on Xe3P and lacks most or all graphics-specific functional units.
Why it matters
- decision Operators with air-cooled halls can put the card on an evaluation list now, but sampling with no price or launch date keeps it out of a capacity plan.
- capability Eight GPUs at 480GB each hold the 8-bit weights of a one-trillion-parameter model in about 26% of their memory, in a box that needs only air.
- contradiction Intel lists latency-sensitive workloads next to multi-tenant serving, yet small batches are where this memory system leaves most of the FP8 peak idle.
- exposure Adopters carry Intel's software risk: multi-GPU serving depends on a stack Tom's says Intel needs, from a vendor whose last data-center GPU line failed.
Tom's Hardware reports that customer sampling is in progress and that Intel did not provide details of a broad launch [10]. Phoronix expects upstream Linux support to be solid "by the time these accelerators are shipping at scale" [22]. Neither article includes a price.
The 1.3 PFLOPS figure is a "theoretical peak performance target" [4]. Divide it by the 1.5 TB/s of bandwidth [5] and the chip needs about 867 floating-point operations for every byte it reads from memory [14]. Generating a token rereads the model's weights, so in our view a single request stream will hit the bandwidth limit long before the FP8 limit. A dense model that filled a card's 480GB would need 0.32 seconds just to be read once [2][15]. The peak transfers only to a workload that batches many requests together.
Against Rubin the gap is large. Tom's puts a Rubin GPU at a theoretical 17.5 PFLOPS of FP8 [8]. That is 13.5 times the D-Series target [16]. A server with eight D-Series GPUs totals 10.4 PFLOPS [17], still short of one Rubin. Tom's adds that each Rubin chip requires liquid cooling and likely has a TGP measured in kilowatts [9]. The fair comparison is an air-cooled HGX-class server [6]. For a hall that cannot take liquid, we think the card is a sound tradeoff, and we would revise that once someone publishes measured throughput per watt.
Software is the open item. Tom's says that inference spread across several GPUs, presumably acting as one, needs a strong software stack, and Intel points to the common Xe software foundation it already uses across iGPUs and discrete GPUs [21]. Phoronix says upstream Linux driver support has been coming along well [22].
What to watch
- Intel publishing a price and broad launch date for GPU D-Series, beyond the current customer sampling.
- Measured tokens per second at stated batch sizes from a sampling customer, which would test the 1.3 PFLOPS target against the 1.5 TB/s limit.
- Whether upstream Linux driver support is complete before volume shipments, as Phoronix expects.
Clarity's read
What the record supports and how the coverage leans. The claims behind it follow.
Reality
- Evidence35
- Adoption5
- Hype gap+10
- Incentives55
- Confidence60
Claim ledger
Ranked by verification strength, evidence, and original report placement.
- [1]
At OCP 2026 Intel gave Crescent Island the name Intel GPU D-Series.
ReportedSupportedSource: Tom's Hardware2 sources— create a free account to open themView cited source - [2]
Intel will release GPU D-Series products in an air-cooled PCIe form factor with a TDP of 350W and up to 480GB of LPDDR5X memory.
ReportedSupportedSource: Tom's Hardware2 sources— create a free account to open themView cited source - [3]
The Intel GPU D Series is headlined by the GPU D270 flagship model, with 480GB of LPDDR5X per card, a 350 Watt air-cooled rating, PCI Express 5.0, 32 Xe3P cores and 256 XMX Xe3P matrix engines.
- [4]
Intel shared a theoretical peak performance target for the chip for the first time: 1.3 PFLOPS of FP8.
- [5]
Intel disclosed the final memory bandwidth for these AI inference accelerators: 1.5 TB/s.
- [6]
GPU D-Series products are meant to be deployed in traditional air-cooled rack servers scaling up to eight GPUs, like Nvidia's HGX systems.
- [7]
In an eight-GPU configuration, Intel says GPU D-Series chips could power inference on models spanning more than one trillion parameters.
- [8]
Each of the 72 Rubin GPUs in Nvidia's Vera Rubin NVL72 rack-scale system can push a theoretical 17.5 PFLOPS of FP8 throughput.
- [9]
Each Rubin chip requires liquid cooling and likely has a TGP measured in kilowatts.
- [10]
Intel says customer sampling of GPU D-Series products is in progress, although it did not provide any details of a broad launch.
- [11]
Intel highlights the chip's suitability for "large language models, long-context inference, and concurrent inference services," creating a foundation for "multi-tenant AI services, robotics, and other latency-sensitive workloads."
- [12]
Crescent Island is the first chip built on Intel's Xe3P architecture, and it lacks most or all of the graphics-specific functional units of a true GPU.
- [13]
Tom's Hardware recalls the failure of the Data Center GPU Max family (Ponte Vecchio) and its mothballed follow-ons, and a series of silicon acquisitions that failed to form a coherent AI strategy.
- [14]
1.3 PFLOPS over 1.5 TB/s is about 867 floating-point operations per byte of memory bandwidth.
- [15]
Reading 480GB once at 1.5 TB/s takes about 0.32 seconds.
- [16]
A Rubin GPU's 17.5 PFLOPS FP8 peak is about 13.5 times the D-Series 1.3 PFLOPS target.
- [17]
Eight D-Series GPUs at 1.3 PFLOPS each total 10.4 PFLOPS of FP8 peak, below one Rubin GPU's 17.5 PFLOPS.
- [18]
Eight GPUs at 480GB each give 3,840GB of memory.
- [19]
The weights of a one-trillion-parameter model at 8 bits (1 byte) each take about 1,000GB.
- [20]
About 1,000GB of weights is roughly 26% of 3,840GB.
- [21]
Tom's Hardware says distributed inference in which multiple GPUs presumably act as one needs a robust software stack; Intel highlights the common Xe software foundation it has built for AI across Xe Cores in iGPUs and discrete GPU products.
ReportedInsufficientSource: Tom's Hardware, citing Intel2 sources— create a free account to open themView cited source - [22]
Linux driver support for Crescent Island has been coming along well upstream, so it should have great open-source, upstream support by the time these accelerators are shipping at scale.
Sources
2 independent publishers whose own reporting we read for this story.
- phoronix.comIntel Announces The GPU D Series For Crescent Island
1 article · October 12, 2026
- tomshardware.comIntel's Crescent Island AI accelerator officially powers new GPU D-Series products
1 article · October 12, 2026
Topics and entities
Follow any of these and your For You feed starts watching them — no settings page required.