Build1 publisher3 min readPublished
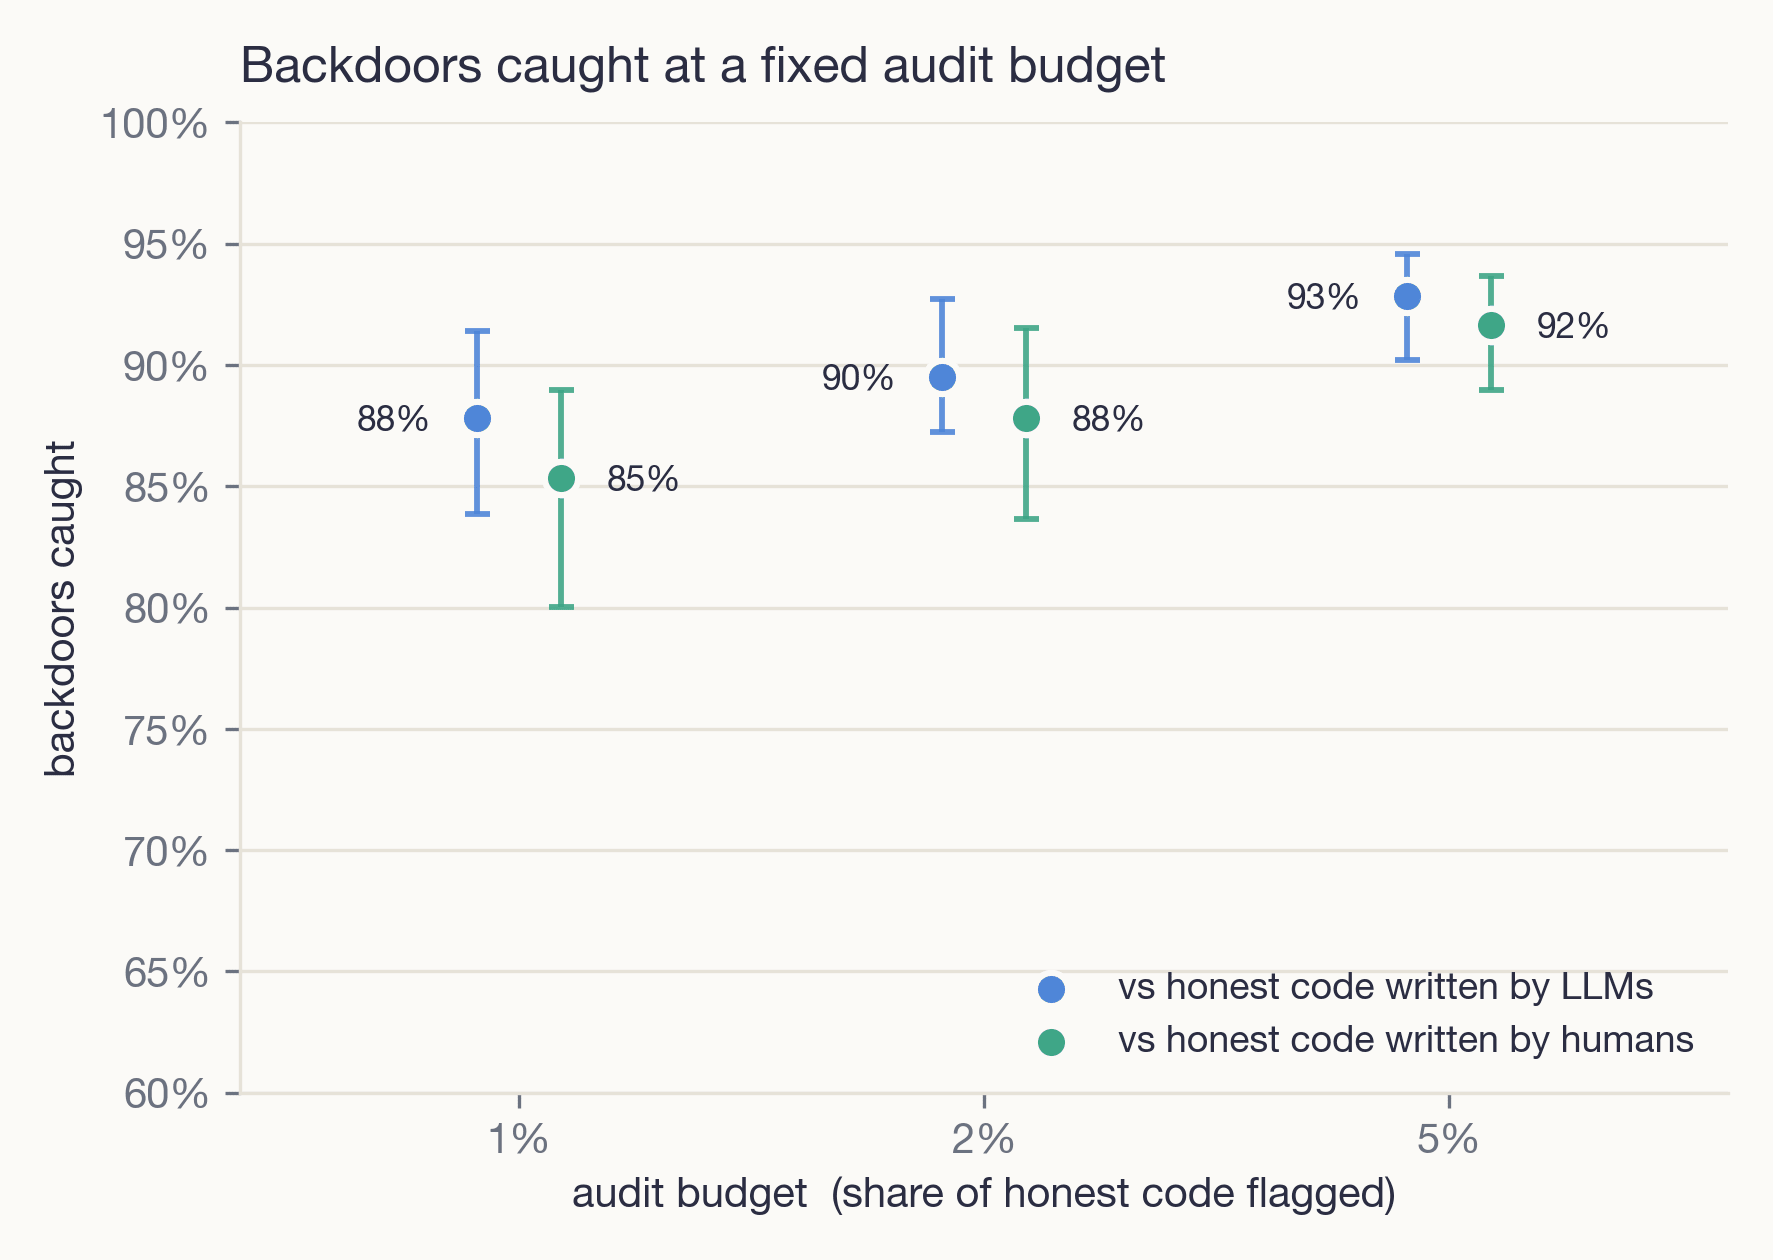
One yes/no question catches 90% of APPS backdoors at a 2% audit budget
A pilot posted on LessWrong scored ControlArena's backdoor set with a single typed probability from TypeSafe's Jev, reaching AUROC 0.976 for about four cents per thousand submissions on $5 of credit and no baseline run of its own.
The Engineer · Build desk
What happened
- TypeSafe AI's Jev returns typed, structured outputs with confidence scores instead of free-form text, and a pilot posted on LessWrong wired a single yes/no question to it as a trusted monitor.
- That one question reached AUROC 0.976 against LLM-written honest code and caught 90% of planted backdoors at a 2% false-positive rate on ControlArena's filtered APPS set.
- Re-scoring the same code moved suspicion scores by 0.008 on average, and 92% of the examples in the top-10% flagged audit set were the same across all calls.
- Comments that told the monitor what to score, injected a security approval, or imitated an output tag with wrong results lowered suspicion on backdoored code by no more than 0.014.
- The author ran the pilot on $5 of credit in 15 hours and decided up front not to run an LLM baseline, so the o3-mini figures it is measured against come from a published paper.
Compiled by The EngineerSomething wrong?How this is made
Why it matters
- cost With input-only billing, the scoring pass stops being the budget question in trusted monitoring; what a deployer pays for is the slice of submissions routed to a human reviewer at the chosen false-positive rate.
- exposure Removing free-text output takes away the channel a jailbreak steers, and leaves the defender's own criteria wording and threshold calibration as the parts an attacker has to move.
- decision Teams running a prompted LLM monitor now have a cheap candidate to test against it, and that test has to use their own honest-code distribution, since 0.976 was scored against LLM-written honest solutions.
- constraint Parity with a reasoning monitor cannot be settled from this data, so anyone who needs that claim has to pay for the baseline run the pilot skipped.
A trusted monitor is only useful if a threshold set once still means the same thing a week later. The write-up puts the requirement plainly: the monitor has to be cheap enough to run on everything and consistent enough that a fixed threshold means the same thing every single time [8]. In this setting the untrusted model writes a Python solution to a competitive programming problem, and a backdoored one passes every test while returning a wrong answer on one secret input the attacker already chose [14]. Fix the false-positive rate at 2% and the top 2% of scores go to a person [15].
The re-scoring test implies that about 8% of the top-decile audit set changes between runs on identical input [2].
The usual trusted monitor is a smaller LLM with a prompt, and the post lists three weaknesses: it costs money per call, its score drifts between calls, and the prompt is the artifact a jailbreak targets [9]. Jev is trained with RLCD, reinforcement learning for calibrated decisions, and answers typed questions with probabilities: a Noul returns P(yes), a Choice returns a distribution over preset options, a Score returns a position on a rubric [10]. No free text is generated, so there is no instruction pathway to attack [11]. The attacker still writes what the model reads. The three injections went into the code and its comments [7].
The whole monitor is one Noul over a JSON state of problem statement plus submission, roughly 1,050 tokens, with no few-shot examples and no system prompt [16]. Input is billed at $0.042 per million tokens and output is free [11]. That works out to $0.0000441 a submission, or 4.4 cents per thousand [1], which is the roughly $0.04 the post reports [5].
The o3-mini comparison rests on published figures, not on a baseline run here. The 0.976 was scored against H1, the LLM-written correct solutions from RoganInglis/control-tax, matched to the same problems [3][19]. The 0.92 to 0.96 range for o3-mini with chain of thought comes from the Control Tax paper, Terekhov et al., 2025 [4]. The author, who set out to test Jev as a cheap non-reasoning alternative [2], wrote that "the comparisons to published numbers below are for positioning only, but not really for measurements" [13].
The backdoored solutions are LLM-written and run about 1.6x longer than human ones, so a monitor could be scoring length while appearing to score intent. H2 is the human APPS solutions the Control Tax paper used [19]. The post gives the AUROC for the LLM-written honest set.
For that number to move into a production pipeline, several things have to hold. Honest code there would have to look like LLM-written honest code. Planted backdoors would have to look like ControlArena's, each of which ships its secret input, verified to pass the tests and fail on that input [18]. And the criteria text, written after reading about 100 backdoored and 100 honest examples [17], would have to keep discriminating on submissions far longer than a competitive programming answer; the evaluation used 150 dev rows and 600 backdoor rows, split by problem [20].
What to watch
- An LLM baseline run on the same 600 backdoor rows would turn the o3-mini comparison into a measurement.
- The AUROC against H2, the human-written APPS solutions, would show how much of the signal is code length.
- Results on codebase-scale submissions rather than 1,050-token competitive programming answers.